
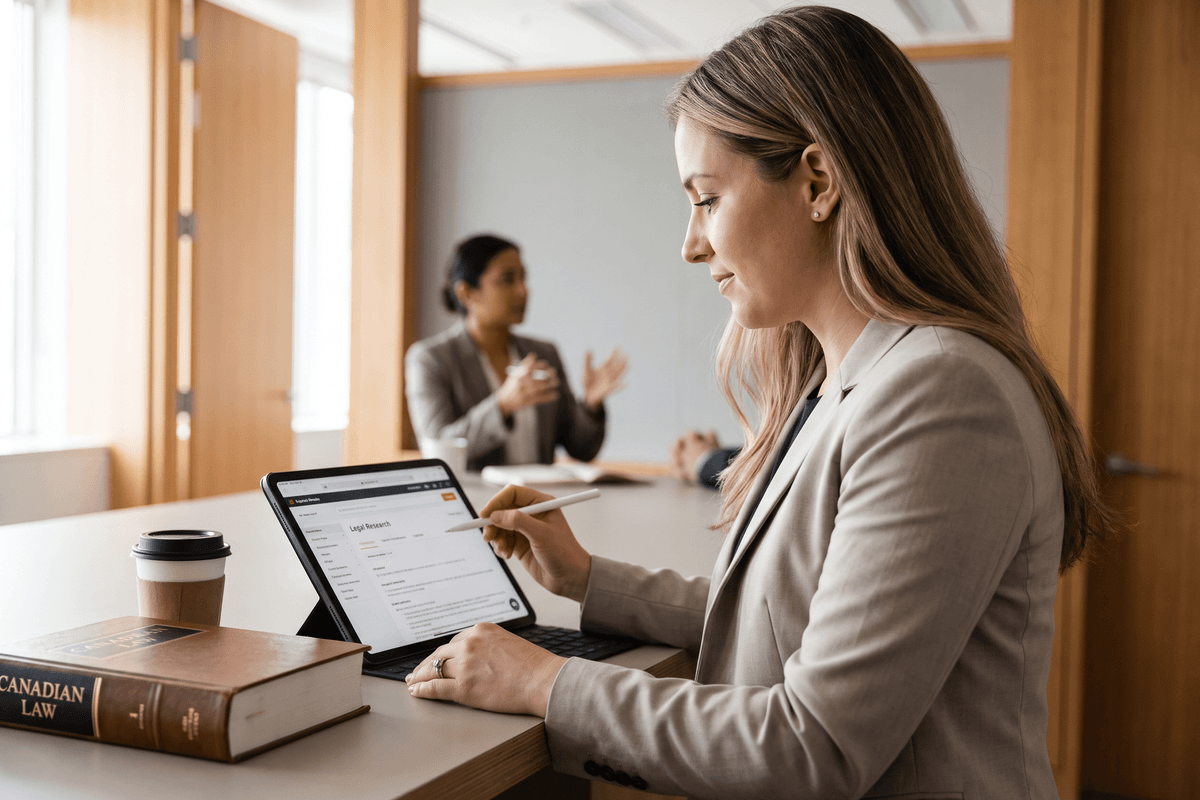


When generative artificial intelligence burst into the mainstream legal consciousness, the initial corporate impulse was simple: take leading public large language models (LLMs) and graft legal prompts onto their front ends. But that first wave of off-the-shelf experimentation rapidly ran into the unyielding realities of Canadian legal practice—hallucinations, opaque reasoning, cross-border data vulnerability, and strict professional conduct obligations. Now, the enterprise legal tech landscape is undergoing a structural transformation. Rather than relying solely on third-party foundational models, major legal technology providers are investing heavily in proprietary, domain-specific artificial intelligence architectures.
According to an in-depth report by Canadian Lawyer Magazine on Thomson Reuters' AI strategy, the information giant has moved to develop custom, domain-specific AI models specifically tuned for legal reasoning, research synthesis, and strict adherence to authoritative primary law. By pursuing a hybrid multi-model architecture, the initiative directly tackles the core anxieties that have held Canadian law firms and corporate legal departments back: data sovereignty, factual verifiability, and client confidentiality.
The Multi-Model Imperative: Moving Beyond Generic LLMs
General-purpose models like GPT-4 or Claude excel at broad creative synthesis and conversational interaction. However, Canadian law is an exacting discipline built on precision, jurisdictional nuances, and rigorous citation standards. A general model trained on the open internet cannot inherently distinguish between a overturned trial ruling from the Alberta Court of Justice and binding Supreme Court of Canada precedent—unless it is explicitly engineered to do so through specialized architecture.
Thomson Reuters’ strategy illustrates how legal tech developers are building specialized small language models (SLMs) and retrieval-augmented generation (RAG) engines trained specifically on authoritative legal editorial assets, including the Canadian Abridgment, KeyCite, and centuries of structured case law. Rather than sending raw legal queries to a broad consumer model, a multi-model approach routes tasks intelligently:
- Syntactical and drafting tasks can be routed to high-capacity foundational models operating in isolated, zero-retention enterprise environments.
- Complex statutory interpretation and precedent analysis are handled by proprietary models calibrated specifically for Canadian jurisdictional hierarchies and legal taxonomies.
- Citation validation is enforced through deterministic checking against closed, verified legal databases, eliminating fabricated citations entirely.
"In high-stakes legal research and drafting, proximity to primary law is not an optional feature—it is the baseline requirement. Generic models predict the next likely token; specialized legal AI must verify the underlying authority before generating a single sentence."
Data Sovereignty and the Canadian Regulatory Imperative
For Canadian practitioners, data residency is not an abstract technical preference; it is a critical regulatory and risk management issue. Cross-border data flows are subject to the Personal Information Protection and Electronic Documents Act (PIPEDA), provincial private-sector privacy statutes, and stringent client-lawyer confidentiality rules. Law firms handling cross-border commercial transactions, public-sector procurement, or sensitive litigation cannot afford to expose proprietary client briefs or non-public case strategies to models that could use that data for retraining in foreign cloud environments.
Proprietary enterprise models address this vulnerability by deploying isolated tenant architectures and sovereign cloud compute clusters within Canadian borders. When legal teams query internal precedents, draft transaction covenants, or upload confidential disclosure bundles, the data remains strictly ring-fenced within compliant jurisdictions.
Regulatory Accountability: The Shifting Canadian Standard
The technical evolution of legal AI coincides with a significant tightening of professional regulation across Canada. As detailed in the Law Society of British Columbia’s October 2026 E-Brief, provincial law societies are actively refining oversight frameworks, modernizing practice rules under new statutory governance models like the Legal Professions Act, and enforcing enhanced compliance mandates spanning anti-money laundering (AML) and client identity verification.
These regulatory updates carry direct implications for artificial intelligence adoption:
- Duty of Competence and Verification: Canadian regulators have made it clear that while lawyers may leverage AI tools for efficiency, the ultimate responsibility for the accuracy of any court submission, legal opinion, or transactional instrument remains strictly with the practitioner.
- Supervisory Obligations over Third-Party Tools: Partners and managing counsel must understand the operational safeguards, data retention policies, and failure rates of the technologies they deploy within their firms.
- Compliance and Anti-Money Laundering Safeguards: With enhanced AML scrutiny, firm technology stacks must maintain immutable audit trails showing how client records, source-of-funds verification documents, and due diligence reports are handled and processed.
Comparative Analysis: Generic LLMs vs. Domain-Specific Legal AI
To evaluate technology investments effectively, managing partners and innovation directors must understand the technical and operational divergence between general consumer AI and proprietary legal models:
| Operational Dimension | Off-the-Shelf Generic LLMs | Proprietary / Domain-Specific Legal AI |
|---|---|---|
| Primary Training Data | Broad internet scrape, public forums, mixed-quality general literature. | Curated, authoritative primary case law, statutes, regulations, and annotated treatises. |
| Citation Integrity | Probabilistic prediction; prone to hallucinated citations and phantom authorities. | Deterministic citation matching tied to structured primary databases (e.g., KeyCite, CanLII). |
| Data Residency & Sovereignty | Frequently routed through dynamic global server clusters without territorial guarantees. | Dedicated sovereign cloud instances (e.g., Canadian data centres) with strict zero-retention guarantees. |
| Point-in-Time Statutory Depth | Struggles to trace legislative amendments and historical revisions reliably. | Built-in temporal tracking of enacted, amended, and repealed statutory provisions. |
| Regulatory Compliance Alignment | Requires extensive manual disclaimers and high supervisory overhead. | Built to satisfy Law Society confidentiality standards and enterprise security audits. |
Strategic Implementation for Canadian Firms: Best Practices
As proprietary models enter active deployment across major Canadian national and regional firms, legal leaders must balance competitive advantage with rigorous risk governance. Three actionable steps should guide this transition:
1. Establish Strict Vendor Due Diligence Protocols
Firms should require AI vendors to provide clear documentation regarding their model architectures. Questions must probe whether inputs are used for model training, where data is geographically stored at rest and in transit, and what mechanisms are in place to cross-verify citations against authoritative Canadian judicial records.
2. Redesign Workflow Verification and Billing Realities
With domain-specific AI handling initial research sweeps and draft synthesis in minutes rather than hours, the billable hour model faces renewed structural pressure. Forward-looking firms are leveraging proprietary AI to offer value-based fixed pricing on complex due diligence and early-stage litigation assessments, while institutionalizing mandatory human-in-the-loop review protocols for all generated work product.
3. Align AI Use Policies with Law Society Rules
Ensure internal firm policies align with the latest guidance issued by provincial regulators, including the Law Society of Ontario, the Law Society of British Columbia, and the Law Society of Alberta. Clear internal rules should delineate which classes of documents may be processed through enterprise-grade AI tools and mandate that junior associates understand how to manually audit AI outputs against primary sources.
The Road Ahead: Specialization as the Standard
The move by major legal publishers to engineer proprietary AI models signals the maturation of legal technology. The era of treating generative AI as a novelty or an unvetted drafting assistant is over. As Canadian courts, corporate clients, and law societies raise the bar for digital accountability, the legal profession’s future will belong to secure, sovereign, and domain-specialized systems designed from the ground up for the administration of justice.